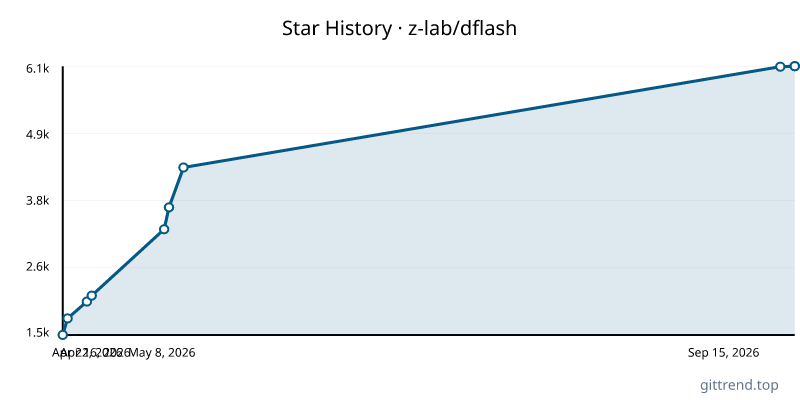
Overview
DFlash is a cutting-edge block diffusion model engineered for flash speculative decoding. It revolutionizes the process of generating text by Large Language Models (LLMs) by enabling efficient and high-quality parallel drafting. This means faster, more responsive AI interactions without sacrificing output quality.
Key Features
- Block Diffusion for Speculative Decoding: DFlash leverages a novel block diffusion approach to predict multiple tokens in parallel, significantly accelerating inference speeds.
- Broad Model Support: Offers pre-trained DFlash draft models for a wide array of popular LLMs, including the Qwen series (Qwen3.5, Qwen3), Llama-3.1, and gpt-oss. Support for even larger models like Qwen3.5-122B and Qwen3.5-397B is on the horizon.
- Multiple Backend Integrations: Seamlessly integrates with popular LLM serving frameworks and libraries such as vLLM, SGLang, Transformers, and MLX (for Apple Silicon), providing flexibility for diverse deployment needs.
- Performance Benchmarking: Comes equipped with comprehensive benchmarking tools to evaluate performance across different backends and datasets, allowing users to optimize their setups.
- Open-Source & Community Driven: The project is open-source, with plans to release the training recipe, empowering users to train their own DFlash draft models. Community feedback is actively encouraged for new model support.
Typical Use Cases
- Accelerated Text Generation: Dramatically speed up response times for chatbots, content creation tools, and any application requiring rapid LLM inference.
- Enhanced User Experience: Provide a smoother, more interactive experience for end-users by reducing latency in AI-powered applications.
- Efficient LLM Serving: Optimize resource utilization and throughput in production environments by enabling faster processing of generation requests.
- Research and Development: Serve as a foundational component for researchers exploring novel techniques in efficient LLM inference and speculative decoding.
- On-Device AI (Apple Silicon): Leverage the optimized MLX backend for fast LLM inference directly on Apple Silicon devices.