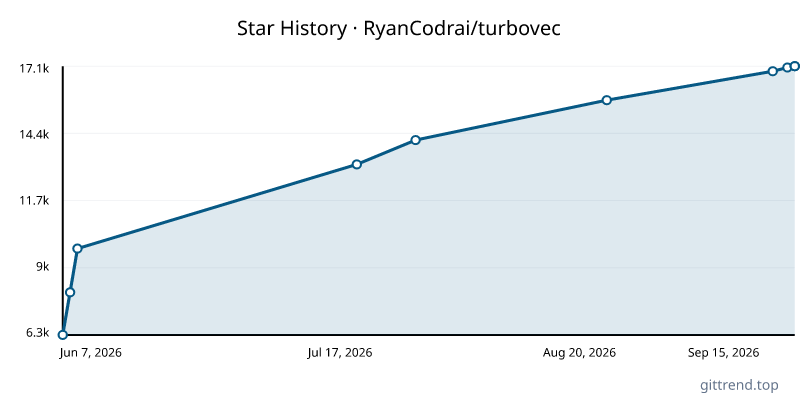
Overview
TurboVec is a high-performance vector index built on Google Research's TurboQuant algorithm. Written in Rust with seamless Python bindings, it offers unparalleled compression and speed for vector search, significantly outperforming traditional methods like FAISS. TurboVec is designed for applications where memory efficiency, lightning-fast search, and privacy are paramount, making it an ideal choice for building robust Retrieval-Augmented Generation (RAG) systems.
Key Features
- Extreme Compression: Reduces memory footprint by up to 16x. A 10 million document corpus that typically requires 31 GB of RAM as float32 can be stored in just 4 GB using TurboVec.
- Blazing Fast Search: Outperforms FAISS's
IndexPQFastScanby 12–20% on ARM and matches or exceeds it on x86, thanks to hand-written NEON and AVX-512BW SIMD kernels. - Online Ingest & No Training: Vectors are indexed as they are added, eliminating the need for separate training phases, parameter tuning, or index rebuilds as your dataset grows.
- Efficient Filtered Search: Supports filtering results at search time via an ID allowlist or bitmask directly within the SIMD kernel. This ensures you always get up to
kresults from the allowed set without over-fetching or sacrificing recall. - Purely Local: Operates entirely on your machine or VPC, ensuring data privacy and control.
- Stable IDs & Deletions: The
IdMapIndexvariant provides stable, user-defined 64-bit IDs and supports efficient O(1) deletion by ID. - Broad Framework Integration: Offers drop-in replacements for popular RAG frameworks like LangChain, LlamaIndex, Haystack, and Agno.
Typical Use Cases
TurboVec is perfectly suited for:
- Privacy-Conscious RAG: Building secure RAG pipelines where data must remain on-premises or within a private network.
- Memory-Constrained Applications: Deploying vector search on devices with limited RAM, such as edge devices or servers with strict memory budgets.
- Low-Latency Search: Achieving sub-millisecond search response times for real-time recommendation systems, semantic search engines, or anomaly detection.
- Large-Scale Embeddings: Efficiently indexing and querying massive collections of embeddings generated by models like OpenAI's
text-embedding-ada-002or others. - Hybrid Search Architectures: Combining TurboVec's dense retrieval capabilities with traditional search methods (e.g., BM25, SQL) for enhanced relevance.